This is Imura from COGNANO. Previously, I wrote about the "Limitations of Biotechnology Hindered by the Multitude of Subjects". I would like to understand the whole organism, which has 40 trillion cells in its body and 30,000 kinds of basic genes alone. 、、、、 However, it is difficult to see it all at once, and it is difficult to break it down to see only one kind of gene, one kind of cell, or one kind of organism. I was talking about the bio method of digging into just one type of cell. It would take an enormous amount of time.
This time, I will talk about the limits of biotechnology, which are created by the sense of causality. Using cancer as an example,...
Cancer cells
Cancer is "a group of cells whose number and arrangement are so disordered as to cause inconvenience. It seems that there are "adjustment rules" in the society of cells, and we are safe because the cells "behave" by increasing and decreasing in number. In daily life, blood and skin are replaced at high speed. In the case of cancer, not only does "overgrowth" put pressure on the surrounding area, but also "metastasis," a location error that leads to uncontrollable growth. Cancer is definitely a "system error in the cellular society. In fact, we want to understand the whole cellular society including cancer.
What causes it? This is where the deep-seated problem begins: A → B is the basis of cause-and-effect relationships. The cause of cancer (B) must be the gene (A), right? If we want to know the true identity of the "cancer cell," we should find out the gene that causes it, right?
Cancer always appears "somewhere" in the body without the person's knowledge, right?
- Time axis problem
- Spatial Axis Problem
It is very difficult to answer the two basic questions.
When did the cancer start, one year ago or five years ago? No way, was it there when you were born? How did it "take the form of cancer we see today?" It could have started out as a combination of multiple cells, or it could have started with one type of cell and branched off. The inability to observe the time series in sequence is a major hurdle in cancer research.
When we consider the spatial axis, it becomes even more difficult to understand. When we think spatially, we say "cancer cell," but is it really one type? Are the surrounding cells not contributing to the abnormal state? If so, are the surrounding cells not called "cancer"? There is no clear explanation for either of these questions. The photo shows SKBR3, a breast cancer cell line (patient-derived "cancer cells" that can be cultured in the laboratory). When you see it, you may think, "Oh, these are cancer cells! I think, "Oh, this is a cancer cell! We just have to get rid of them. And in many cases, this idea is not mistaken.
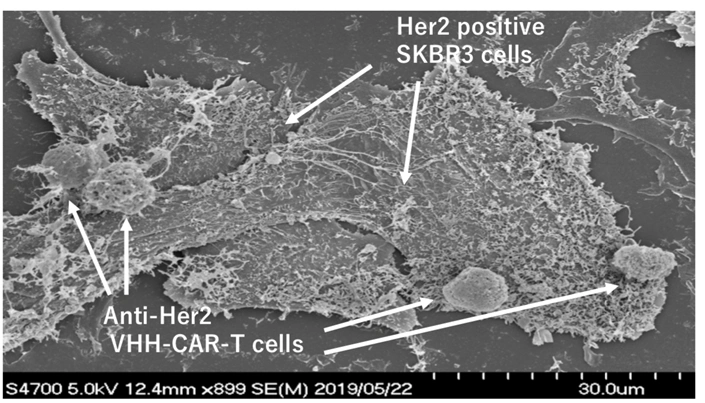
Since expanding the hypothesis too much would make the research untenable, we have had to limit ourselves to the study of "badass cells," which we have tentatively determined to be a single type for now. It is like capturing one enemy soldier and interrogating the entire enemy army. Cancer research starts in a "provisional" setting in terms of time and space. This is the first limitation.
Are genes the cause?
It is generally believed that cancer is caused by genetic abnormalities, but is this true? A few decades ago, when it was discovered that introducing a certain gene into the genome caused cancer It was said, "We have found the cause of cancer! Certainly, in most cases, cancer cells are accompanied by genetic mutations, and there is no doubt that "genetic abnormalities are important. There is a product with the catchphrase, "Test your genome for cancer susceptibility," which is based on the loose understanding that "cancer is caused by genes. This is based on the loose understanding that cancer is caused by genes. However, these tests only evaluate influencing factors such as "cancer gas pedals" or "cancer brakes," but they cannot point out or diagnose what cancer is. and cannot point out or diagnose the disease. In fact, in the past 15 years or so, with the development of next-generation sequencers, many patient cells have been analyzed genetically and various abnormalities have been pointed out, but no unifying theory has been found that can definitively say, "This is the cause. This history suggests three possibilities (Note: This is my personal opinion)
(1) Cancer cells may not actually be of one type, but rather highly diversified. (Note: This is my personal idea.) (1) Cancer cells may not be one type, but rather highly diversified.
2. have important characteristics that were present in the early stages of the disease already disappeared in cancer patient samples?
3. genetic abnormalities are not contributing as much as expected. Are non-genetic factors also heavily involved?
If these issues are multi-layered, they cannot be easily elucidated. This is the second limitation.
- → Picking up minute information by examining the cancer and surrounding cells in a cursory manner: single-cell genome sequencing on, say, 1 million cells, rather than taking an average value. Increase detection power with big data. 2.
2.→No cancer cells remain at the time of development: unless a time machine is invented, we are out of luck. - →Expand the scope of investigation to include macromolecules other than genes: data on lipids and sugar chains is too much work, and currently the only category that can be informative is genes. 、、、、
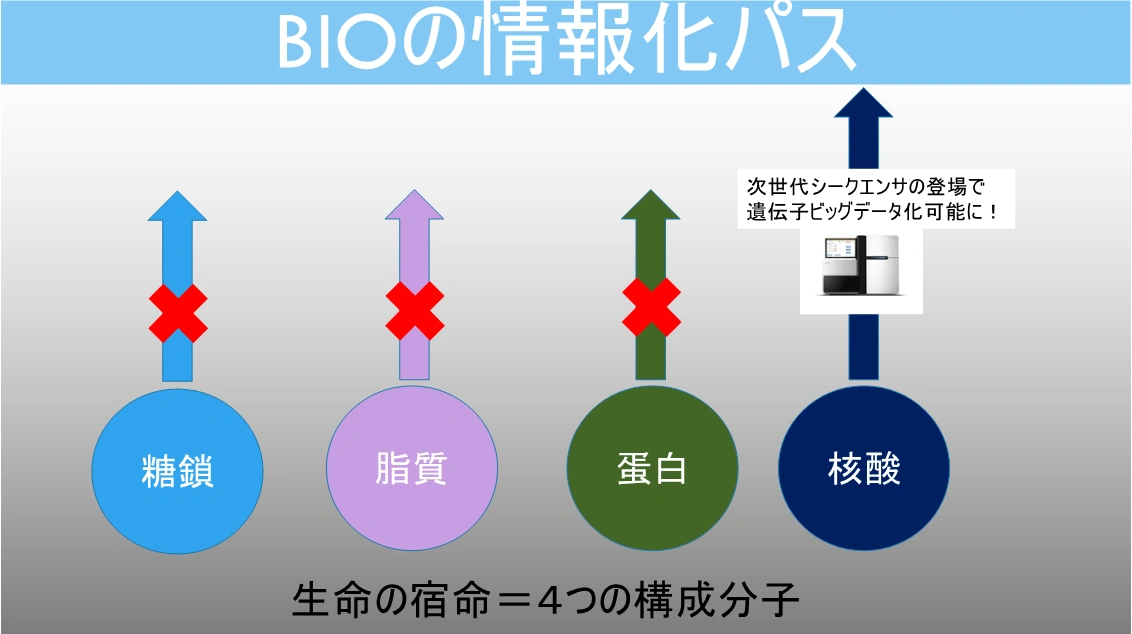
Life is composed of glycans, lipids, proteins, and nucleic acids, and as a substance, one of these substances must be analyzed. Of the four substances, so far only nucleic acids (genes) can be converted into information at high speed. On the other hand, "structure," an important property of proteins, has been a difficult task, but it is still fresh in our memory that AlphaFold2 reached the algorithmic prediction. Real structure analysis was that much harder. Glycans and lipids are even more difficult.
The maze of causality
The first strategy is based on the hypothesis that the direction was correct, but the detection sensitivity was insufficient. The "machines might be able to detect it". deep mining will help us to find the unknown "hard to see".
The "deep" factor could be uncovered by mining, which is an unknown and "hard to see" factor. Programmers are already leading research in this direction. It is important to note, however, that it relies on the hypothesis that "genetic variation was highly contributing".
2 is a painful task, and real samples going back in time are not available. Causality becomes a much more difficult problem when the time series is not known. If the initial characteristics have already been lost, then ・・・・ is almost unrealistic.
3, How can we target something other than genes? That means linking proteins and sugar chains to cancer. Now what to do COGNANO? On to the second part!